A dating app at scale must show each user good candidates within 10 miles, at the moment they open the app, while 75 million people use the app every day.
By the end of this post you will know how to size that system from a few business numbers, why the obvious designs fail (a geo query per swipe, a match check that reads before it writes, a chat that depends on the live connection), and what to build instead: a deck of candidates ranked ahead of time, geohash cells sized to the search radius, one Redis key per pair for matches, and a message store the phone syncs from. Four figures let you try the parts that are easy to get wrong.
The Hard Parts #
Four problems are harder than profiles and matching:
-
Proximity: you need people near the user, and “near” changes when they move. Locations update every few minutes, for 75M daily active users.
-
Cold start: new users have no swipe history. If their first recommendations are bad, they leave within 48 hours.
-
Mutual interest: on Instagram, one person follows and it is done. Here both people must swipe right, so the model must predict attraction in both directions.
-
Chat delivery: after a match, the first message must not be lost. If it is lost, the user can leave the app.
Requirements #
What the App Does #
| Feature | User Sees | Engineering Complexity |
|---|---|---|
| Recommendations | “Here are people near you” | Very High |
| Location Updates | Background sync | High |
| Chat | Message delivery | Medium |
| Matching | “It’s a Match!” | Medium |
| Profile CRUD | Edit bio, photos | Low |
| Notifications | Push alerts | Low |
Recommendations are about 80% of the system’s complexity.
The Load #
Derive the load from business numbers.
Assumptions:
- 75M DAU (an upper bound: Tinder has reported about 75M monthly active users)
- Average session: 7 minutes
- Average swipes per session: 50
- Peak hours: 8 PM - 11 PM local time (3-hour window)
Swipes:
Daily swipes = 75M × 50 = 3.75 billion swipes/day
             ≈ 2 billion (not every daily user swipes a full session)

Peak QPS for swipes = (2B × 0.4) / (3 hours × 3600)
                    = 800M / 10,800
                    ≈ 74,000 swipes/second at peak
Each swipe can cause up to four operations: a write to record it, a read to check for a match, a deck fetch if the queue is low, and a match notification. So the effective load is up to 4× the swipe rate, about 300,000 operations/second at peak.
Location updates:
If 30% of DAU has location services on = 22.5M users
Update every 5 minutes = 22.5M / 300 = 75,000 location updates/second
Chat:
10% of DAU sends messages = 7.5M users
Average 20 messages/day = 150M messages/day
Peak: 150M × 0.4 / 10,800 ≈ 5,500 messages/second
The Latency Targets #
| Metric | Target | Why |
|---|---|---|
| Recommendation latency P99 | < 100ms | User is swiping |
| Match notification latency P99 | < 500ms | A match should feel instant |
| Message delivery latency P99 | < 200ms | Chat feels broken otherwise |
| Photo load time P50 | < 300ms | First impression is visual |
| Location update lag | < 5 min | Accuracy vs. cost |
The System at a Glance #
Each user action takes its own path through the system. Pick one to step through the services it touches, the command at each hop, its peak load, and its latency target.
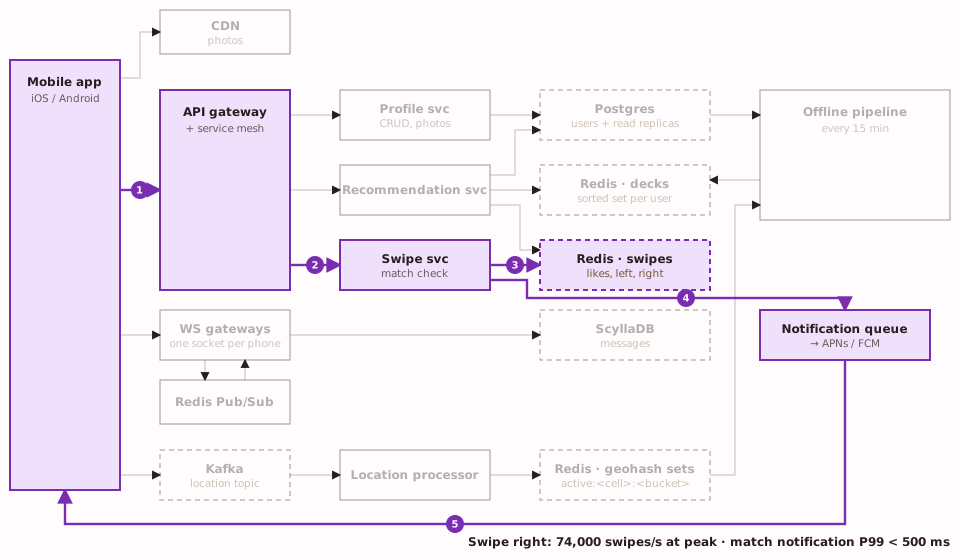
The rest of the post explains these paths one at a time. It starts with recommendations, the feature with the highest complexity in the table above. Recommendations decide what to show when someone opens the app.
Recommendations #
Why Not Query per Request #
The direct approach is one SQL query per request:
SELECT * FROM users
WHERE ST_DWithin(location, user_location, 50000)  -- 50km
AND age BETWEEN 25 AND 35
AND gender = 'F'
AND last_active > NOW() - INTERVAL '7 days'
LIMIT 200;
It fails on both sides. On the read side, at 74,000 swipes per second, a geo query plus a ranking model per request cannot meet the 100 ms P99 target. On the write side, at 75K location updates per second, each update writes a new row version and a new GiST index entry, and vacuum has to clean up the old ones. One Postgres primary has trouble keeping up with that write rate.
Rank Ahead of Time, Serve the Top #
Every 15 minutes, an offline pipeline finds candidates in nearby geohash cells, ranks them, and writes each user’s top 200 into a Redis sorted set: their deck. When the user opens the app, the service pops the top 10 (ZPOPMAX deck:u42 10), drops anyone swiped since the deck was built, and returns the cards well inside the 100 ms P99 target. A swipe does not touch the deck. It is one small write, and the phone pops 10 more after its last card. At 74,000 swipes per second, that is about 7,400 pops per second.
The expensive work, finding nearby people and scoring them, runs offline. The next sections cover both steps.
Candidate Generation: Geohash Cells #
The offline pipeline still needs “people near this user”, without a geo index in Postgres. It keeps one Redis set per geohash cell and time bucket:
# Divide the world into geohash cells (precision 5 is 4.9 km × 4.9 km at the
# equator; cells get narrower east-west as you move away from it)
# Store users in Redis sets keyed by geohash + time bucket

def get_candidates(user):
    user_geohash = geohash.encode(user.lat, user.lng, precision=5)
    neighbor_cells = geohash.neighbors(user_geohash)

    candidates = []
    for cell in [user_geohash] + neighbor_cells:
        # Time bucket ensures we only see recently active users
        bucket = get_time_bucket(hours=24)
        key = f"active:{cell}:{bucket}"
        candidates.extend(redis.smembers(key))

    return candidates[:500]  # Cap for ranking phase
Why this works:
- One
SMEMBERSper cell, so 9 reads per request.SMEMBERSis O(N) in the size of the set, so in a dense cell read a sample withSRANDMEMBER key countinstead. - Time bucketing drops stale users, as long as each bucket key has a TTL.
- The write path is pipelined
SADDs, and one Redis node handles well over 100K of those per second.
The distance that the 9 cells cover is easy to get wrong. Nine square cells do not form a circle, and a cell’s width depends on latitude. Guess first, then move the user, the radius, and the precision:
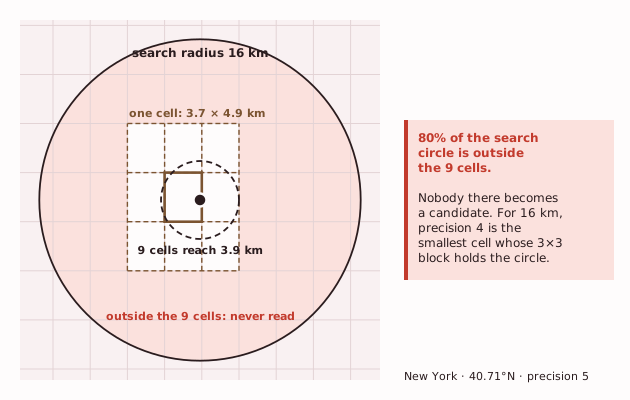
In the worst case, when the user stands in a corner of their cell, the block reaches only one cell side: 4.9 km at precision 5 on the equator, 3.7 km in New York. That is much less than the 10 miles (16 km) in the first paragraph. So choose the precision from the radius: use the smallest cells whose 3×3 block still holds the circle, then drop candidates by real distance. Redis GEOSEARCH works the same way. It estimates the cell size from the radius, reads the 3×3 block, and moves to bigger cells when the block does not cover the search area1.
Keeping the Cells Fresh #
The location pipeline writes those cells. At 75,000 updates/second, it is the most write-heavy path. Pick Location update in Figure 1 to follow it: phone, Kafka as a buffer, the location processor, the geohash sets, and the offline pipeline that rebuilds decks from them.
Location does not need to be real time. A 5-minute lag is fine, so the processor batches its writes:
# Kafka consumer processing location updates
async def process_location_batch(messages):
    # Batch by geohash cell
    updates_by_cell = defaultdict(list)

    for msg in messages:
        user_id = msg['user_id']
        new_hash = geohash.encode(msg['lat'], msg['lng'], precision=5)
        old_hash = await redis.hget(f"user:{user_id}", 'geohash')

        if old_hash != new_hash:
            # User moved to different cell
            updates_by_cell[old_hash].append(('SREM', user_id))
            updates_by_cell[new_hash].append(('SADD', user_id))

            # Update user's stored location
            await redis.hset(f"user:{user_id}", {
                'geohash': new_hash,
                'lat': msg['lat'],
                'lng': msg['lng']
            })

    # Batch Redis operations
    pipe = redis.pipeline()
    for cell, ops in updates_by_cell.items():
        for op, user_id in ops:
            bucket = get_time_bucket(hours=24)
            if op == 'SADD':
                pipe.sadd(f"active:{cell}:{bucket}", user_id)
            else:
                pipe.srem(f"active:{cell}:{bucket}", user_id)

    await pipe.execute()
Ranking: The Bilateral Problem #
A dating app ranks differently from TikTok:
TikTok: P(user likes video)
Tinder: P(user A likes user B) × P(user B likes user A)
You need to predict both directions, and spread attention fairly:
def calculate_match_score(user_a, user_b):
    # How likely is A to swipe right on B?
    a_likes_b = model.predict(user_a.features, user_b.features)

    # How likely is B to swipe right on A?
    b_likes_a = model.predict(user_b.features, user_a.features)

    # We want to maximize mutual matches
    # But also give everyone a fair chance (avoid rich-get-richer)
    mutual_probability = a_likes_b * b_likes_a

    # Factor in B's current queue depth (fairness)
    fairness_boost = 1.0 / (1 + log(user_b.daily_impressions))

    return mutual_probability * fairness_boost
If you rank only on “will this user swipe right”, everyone sees the same top 1% of profiles. Those users get more likes than they can answer, everyone else gets no matches, and people leave.
Matching: Two Swipes at Once #
When both users swipe right, the system must detect the match, notify both users, and create a conversation, with no race conditions at 74K swipes/second.
A and B swipe right on each other within the same few milliseconds. Each request must save its own swipe and check for the other one. Whether the match is found depends on how those two steps are written, and on the order in which the calls reach Redis.
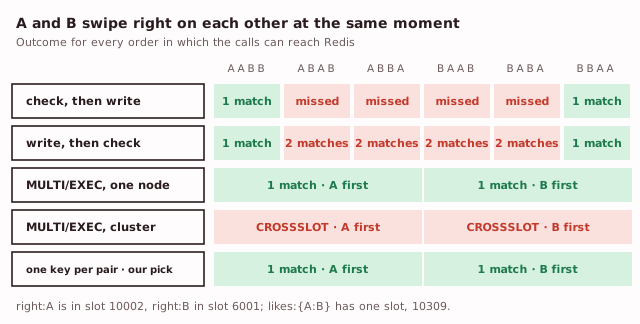
CLUSTER KEYSLOT, and the CROSSSLOT reply is what a Valkey 9.1 cluster returns for this transaction.Checking before writing can miss the match, and a replica that lags the primary has the same effect. Writing before checking can create the match twice. A MULTI/EXEC transaction fixes both on one Redis node, and redis-py’s pipeline() already sends one. On Redis Cluster, though, right:A and right:B hash to different slots, and a transaction may only touch keys in one slot2. One key per pair, with a hash tag, keeps the transaction in one slot:
def record_swipe(swiper_id, target_id, direction):
    if direction == 'left':
        redis.sadd(f"left:{swiper_id}", target_id)
        return None

    # One key per pair. Both users build the same key, and Redis Cluster
    # hashes only the part inside {…}, so the key has a single slot.
    # The deck filter reads this per-user set; the match decision does not.
    redis.sadd(f"right:{swiper_id}", target_id)

    lo, hi = sorted((swiper_id, target_id))
    key = f"likes:{{{lo}:{hi}}}"

    pipe = redis.pipeline()        # transaction=True: MULTI … EXEC
    pipe.sadd(key, swiper_id)
    pipe.scard(key)
    added, likes = pipe.execute()

    if added == 1 and likes == 2:  # true for exactly one of the two swipes
        match_id = create_match(lo, hi)

        # Fan out notifications
        notification_queue.publish({
            'type': 'match',
            'match_id': match_id,
            'users': [lo, hi]
        })

        return match_id

    return None
added == 1 keeps a repeated swipe from creating the match again. The cost is one small key for every pair with at least one like. The per-user sets left:{user} and right:{user} stay for the deck filter.
Chat: The First Message #
Phones switch between WiFi and cellular, WebSocket connections drop silently, and users go offline for days. Through all of that, a message must never be lost or shown twice, and read receipts must sync in real time.
Each phone holds a WebSocket to one gateway pod. Gateways pass messages to each other through Redis Pub/Sub, and every message is stored in ScyllaDB. Pub/Sub delivers at most once and keeps no copy3, so the live path alone cannot meet the first requirement above. Pick a fault and follow the first message:
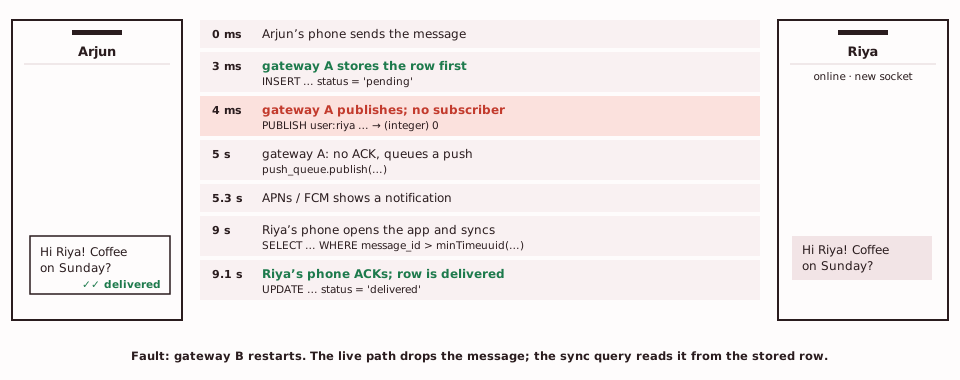
message_id is a real version-1 UUID for 2026-02-14 15:11:07 UTC.Every fault has the same result, because the guarantee depends on two things only, the row in ScyllaDB and the phone’s ACK. A successful socket write is not an ACK. The kernel accepts the bytes even when the phone is gone, and Linux keeps retransmitting for 13 to 30 minutes before it reports the connection dead4.
The Delivery Guarantee #
async def send_message(conversation_id, sender_id, recipient_id, content):
    # timeuuid columns accept only version-1 UUIDs, so not uuid4() or uuid7()
    message_id = uuid1()

    message = {
        'conversation_id': conversation_id,
        'message_id': message_id,
        'sender_id': sender_id,
        'content': content,
        'status': 'pending',
    }

    # 1. Persist first (durability)
    await scylla.insert('messages', message)

    # 2. Try real-time delivery. True only if the phone ACKs message_id
    #    within the timeout, not when the socket write returns.
    delivered = await try_websocket_delivery(recipient_id, message, ack_timeout=5)

    if delivered:
        await scylla.update('messages', message_id, {'status': 'delivered'})
    else:
        # 3. Queue for push notification
        await push_queue.publish({
            'user_id': recipient_id,
            'type': 'new_message',
            'preview': content[:50]
        })

        # 4. Message waits in "pending" until the phone syncs and ACKs

    return message_id
On every connect, the phone asks for messages newer than the newest one it has, and stores them by message_id. That query is what recovers a lost message, and the ID is what stops a message from showing twice.
ScyllaDB schema for messages:
CREATE TABLE messages (
    conversation_id uuid,
    message_id timeuuid,
    sender_id uuid,
    content text,
    status text,
    PRIMARY KEY (conversation_id, message_id)
) WITH CLUSTERING ORDER BY (message_id DESC);
Why ScyllaDB:
- Time-series write pattern (append-only messages)
- High write throughput (100K+ writes/sec per node)
- Natural time-ordering with
timeuuid, a version-1 UUID that contains its creation time5 - Partition by conversation keeps related messages together
Where the Data Is Stored #
| Data Type | Storage | Why |
|---|---|---|
| User profiles | PostgreSQL + Read replicas | ACID for billing, strong consistency for auth |
| User photos | S3 + CloudFront CDN | Low storage cost, global edge delivery |
| Swipe history | Redis (hot) + DynamoDB (cold) | Recent swipes need sub-ms access |
| Messages | ScyllaDB | Write-heavy, time-series, partition by convo |
| Recommendation queues | Redis Sorted Sets | Pre-computed, fast pop operations |
| Geospatial index | Redis Sets (geohash) | One key per cell; SADD/SREM keep up with the write volume |
| Analytics events | Kafka → ClickHouse | Columnar for aggregations |
Infrastructure estimate:
- 50-100 WebSocket gateway pods (100K connections each)
- 20-node ScyllaDB cluster for messages
- 50-node Redis cluster for recommendations
- 10-node PostgreSQL cluster (1 primary, 9 replicas)
- Kafka: 100+ partitions for location topic
What Could Go Wrong #
1. Hot users
A celebrity joins and gets 500,000 swipes in an hour. Their “who liked me” sorted set grows without limit. Fixes:
- Cap the “likes received” list at 10,000
- Sample/aggregate for display
- Rate limit visibility of hot profiles
2. Ghost matches
A and B match, and A unmatches at once. B gets the “It’s a Match!” notification but cannot find the match. Fixes:
- Add
matched_attimestamp, grace period before display - Notification includes match_id, client verifies before showing
3. Location spoofing
Users fake GPS to see profiles in other cities. Fixes:
- IP geolocation cross-reference
- Impossible travel detection (NYC to Tokyo in 1 hour)
- Cellular tower triangulation on mobile
4. Running out of profiles
In small towns, users run out of profiles in 2 days. Fixes:
- Gradually expand radius
- Show profiles from nearby cities with disclosure
- “No more profiles nearby—expand your distance?”
Takeaways #
- Size the system from business numbers first: 74,000 swipes/s, 75,000 location updates/s, and 5,500 messages/s at peak.
- Keep ranking off the request path. A per-user deck in a sorted set turns “open the app” into one pop.
- Size geohash cells from the search radius. Nine precision-5 cells around a New Yorker reach 3.7 to 5.6 km, much less than 10 miles (16 km).
- Save the swipe and check for the match in one transaction on one key. On Redis Cluster, that means one key per pair.
- Store the message first, count it delivered only when the phone ACKs, and let the phone sync from the store.
These questions are still open, and each one needs both product and engineering decisions:
- How to balance attractive profiles (engagement) against compatible ones (retention).
- How to stop the top 10% of profiles from getting most of the matches.
- How to detect and handle bad actors at scale.
-
https://github.com/redis/redis/blob/unstable/src/geohash_helper.c,
geohashCalculateAreasByShapeWGS84↩︎ -
https://redis.io/docs/latest/develop/using-commands/multi-key-operations/ ↩︎
-
https://redis.io/docs/latest/develop/pubsub/#delivery-semantics ↩︎
-
https://man7.org/linux/man-pages/man7/tcp.7.html,
tcp_retries2↩︎ -
https://docs.datastax.com/en/cql-oss/3.x/cql/cql_reference/uuid_type_r.html ↩︎